Before opening a tool for the task behind “text editor encoding detection,” settle one point: treat automatic encoding detection as a lead and confirm it with bytes and representative characters. The controlled case is UTF-8 samples with and without BOM containing 髙, 﨑, ①, and an emoji, plus a Shift_JIS sample limited to encodable kanji, kana, and half-width katakana. A pass must demonstrate this outcome: complete the article-specific sample with separate evidence for BOM, detection label, representative character, save-as copy, reopened equality. The excluded range is stated separately: repairing already-corrupted text and perfect detection of every encoding.
Decision: Treat automatic encoding detection as a lead and confirm it with bytes and representative characters
Define the stop line on a recoverable copy. Evidence for BOM must exist before the run can advance to reopened equality.
The article-specific evidence card has these fields: BOM, detection label, representative character, save-as copy, reopened equality. Do not count the following excluded range as evidence: repairing already-corrupted text and perfect detection of every encoding.
One case, one authority, one result
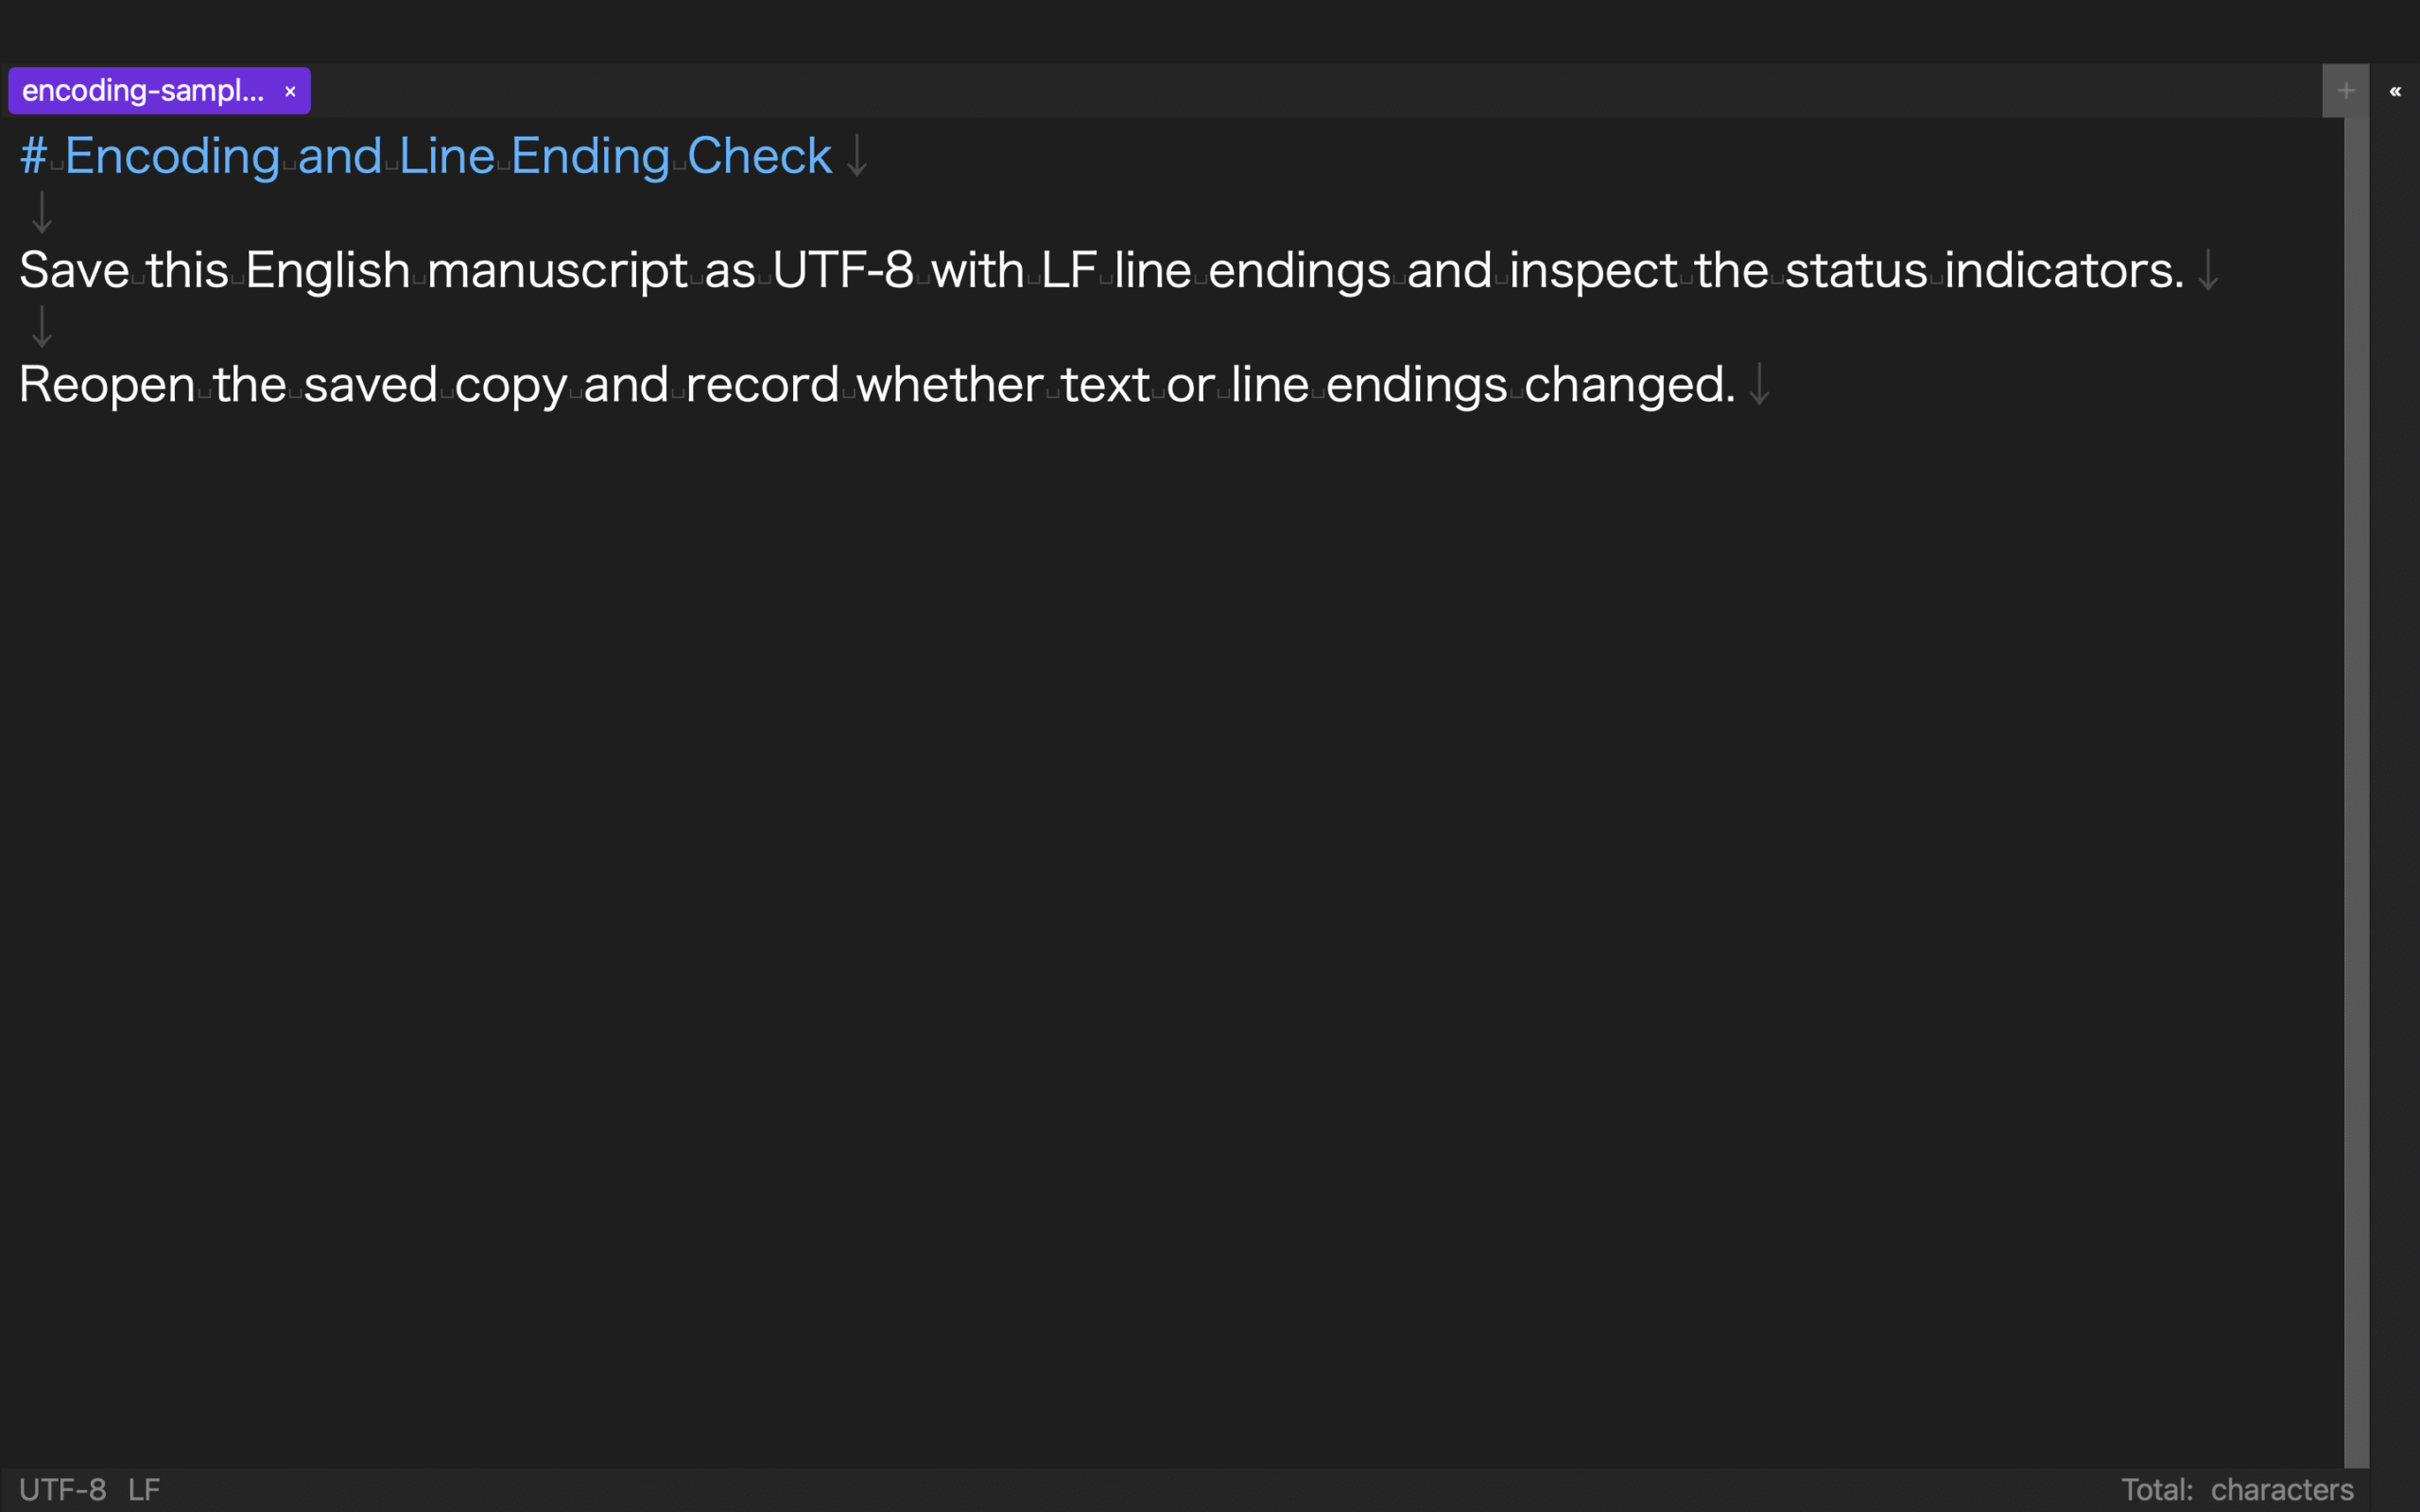
Use UTF-8 samples with and without BOM containing 髙, 﨑, ①, and an emoji; use a separate Shift_JIS sample containing only encodable kanji, kana, and half-width katakana. Record initial bytes, view the detected encoding, inspect representative characters in context, save to a different name, and compare after reopening. Never trust the label alone, overwrite through a conversion warning, or accept changed characters after reopen.
This case addresses the failure behind the search: losing the authoritative input or acceptance evidence while trying to treat automatic encoding detection as a lead and confirm it with bytes and representative characters. Name the source, working copy, and delivered or reopened result so that another editor can locate each one without relying on a filename such as final.
A reproducible first pass
Use the following product-independent sequence on the named sample. It is an acceptance method, not a claim that Rune Studio has already completed this particular case.
- 1. Record each sample's initial bytes. Attach the observed BOM evidence to this step.
- 2. View the detected encoding. Attach the observed detection label evidence to this step.
- 3. Inspect representative characters in context. Attach the observed representative character evidence to this step.
- 4. Save under another name. Attach the observed save-as copy evidence to this step.
- 5. Reopen and compare with the source sample. Attach the observed reopened equality evidence to this step.
How to mark the run
Do not infer one row from another. Record pass, revision, or not tested beside the actual target, date, output path or artifact ID.
- BOM — expected state: written before the run; hold the row if only the detection label is inspected.
- Detection label — expected state: written before the run; hold the row if a conversion warning is overwritten.
- Representative character — expected state: written before the run; hold the row if representative characters change after reopen.
- Save-as copy — expected state: written before the run; hold the row if only the detection label is inspected.
- Reopened equality — expected state: written before the run; hold the row if a conversion warning is overwritten.
Where this workflow must stop
A second pass is meaningful only when its source and changed condition remain identifiable. Keep the earlier result and append the retest instead of replacing the failed row.
- 1. Only the detection label is inspected; change only the responsible condition.
- 2. A conversion warning is overwritten; return to the named source.
- 3. Representative characters change after reopen; preserve the failed artifact.
Rune Studio as a bounded candidate
Current product documentation covers capabilities relevant when you need to identify common Japanese encodings and line endings and verify a separately saved copy. That scope can justify a trial, but it does not show that UTF-8 samples with and without BOM containing 髙, 﨑, ①, and an emoji, plus a Shift_JIS sample limited to encodable kanji, kana, and half-width katakana passed this article's acceptance card.
Rune Studio is a plausible candidate when fewer source, setting, or reference handoffs help you treat automatic encoding detection as a lead and confirm it with bytes and representative characters. Use another tool or destination check for the excluded range stated here: repairing already-corrupted text and perfect detection of every encoding.
The decision to keep
For the search phrase “text editor encoding detection,” the conclusion is to treat automatic encoding detection as a lead and confirm it with bytes and representative characters. The result is accepted only when the record establishes this outcome: complete the article-specific sample with separate evidence for BOM, detection label, representative character, save-as copy, reopened equality.
Begin here: prepare three byte-identified samples with encoding-appropriate representative characters. If only the detection label is inspected, stop at that row and return to its source. Check the Rune Studio product page for the current Mac feature scope before applying the same acceptance card to a product trial.